-
0:00
Introduction
-
0:25
How can you build more infrastructure to serve more AI
-
1:01
The network is critical for GPU utilization
-
1:31
DriveNets provides the full-stack suite for GPU interconnect
-
2:15
Disaggregated Inferencing and Heterogeneous AI
-
4:00
Scale-Across: Connecting GPUs Across Distant Data Centers
-
5:10
What’s Next: A Preview of SC26
At the 2026 AI Infra Summit, DriveNets’ Dudy Cohen (VP Product Marketing) explores how networking plays a key role in AI infrastructure, from optimizing GPU utilization, supporting scale-across for data centers to enabling heterogeneous AI.
Read the full transcript
We are here in Santa Clara at the AI Infra event.
This year it is packed much more than previous years, and it is no surprise because AI, I think, is the most important and discussed topic on the planet, and AI infrastructure is the enabler for it.
How can we build more infrastructure to serve more people with AI
So everyone is coming here to discuss how can we build more infrastructure to serve more people with AI. And I think one of the topics that are heavily discussed here is the lack of power because we are living in the token economics. No one is talking about flops anymore.
We are talking about tokens. No one, no one is talking about cost anymore. We’re talking about token per dollar and more importantly, token per watt. We want to squeeze more tokens out of the infrastructure we have. We want to squeeze those GPUs that are very expensive to perform the highest they can.
The most expensive resource on Earth is a GPU standing idle
And I think someone said that the most expensive resource on Earth is a GPU standing idle, either if it’s waiting to be powered up because it lacks power, or if it’s waiting for some information that should come through the network that connects it to the other GPUs in the cluster. So the main effort is to make GPU work more. And I think this is what we’re seeing this year, strive to optimize GPU.
DriveNets provides the full-stack suite for GPU interconnect
And this is also what DriveNets is focusing on because we provide the full-stack networking suite for GPU interconnect. It’s not just the switching that we sell. We have launched and demonstrated the Tomahawk 6, new 100% liquid-cooled switch this year. But it’s also the fact that we have full-stack optimization. We go into the NICs and the NIC parameter. We go into the collective communication library and their parameters. And and even as far as the kernel and the workload in order to optimize it. Because at the end of the day, you want everything to work as a single system and you want to get more out of your infrastructure. So this is what we are doing here.
Disaggregated inferencing and building AI infrastructure which is heterogeneous
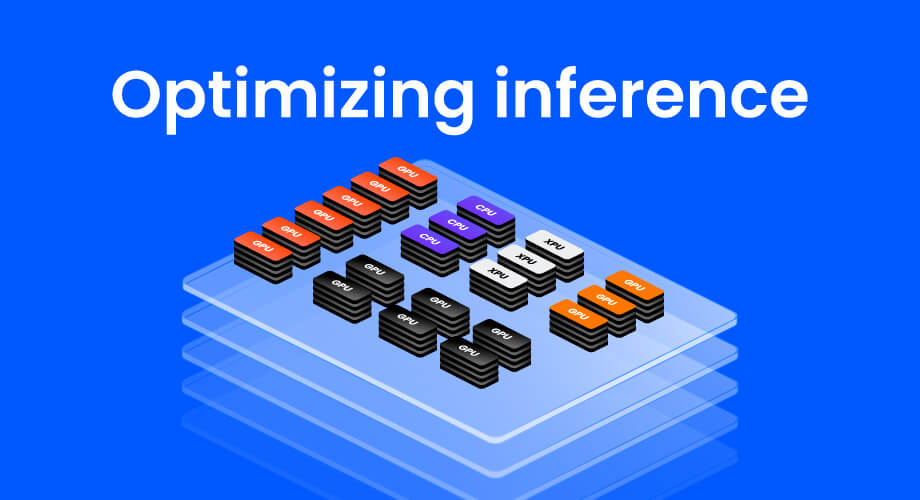
I think one of the trends we see as part of this drive to make GPUs work better is disaggregated inferencing, in which you take the workload, especially in inference, which is becoming the major part of AI today, and you distribute it and disaggregate it to different stages that need different type of specialty ASICs. So we are starting to see operators, NeoClouds, and others building AI infrastructure which is heterogeneous, which— in which there are multiple ASICs or multiple GPU types coexisting in a single cluster, and the workload is bouncing between them, and each stage of the process of inferencing is handled by the most optimized infrastructure. And for this, you need a very special networking infrastructure because networking is key for the great promise of disaggregated inferencing and heterogeneous AI because your network needs to accommodate a much burstier, unexpected traffic pattern.
Your network needs to be there in order to move the KV cache from one ASIC to another, et cetera. And we at DriveNets are focusing on optimizing this environment of disaggregated inferencing, having this full-stack optimization for each type of ASIC. We are working with AMD, for instance, with which we have a reference architecture. We are working with other ASIC vendors in order to optimize the entire stack in order to make this promise of heterogeneous AI come true.
Scale-across solution for geographically distant data centers
Another topic that is being discussed here today and with a lot of customers, and for the same reason of trying to maximize the power resources, is scale across. Because at the end of the day, when you have a data center, at some point you run out of power, but you need more GPUs because the workloads are growing hungrier by the day. And in order to overcome this barrier, we offer a scale-across solution, which is a combination of shallow buffer and deep buffer networking that can connect 2 data centers that are tens of miles apart, even more than 100 miles apart, and distribute the GPUs between the 2 of them. So you can leverage the different power resources you have in multiple data centers. But still look at the entire setup as a single infrastructure, a single GPU cluster. So you can run larger datasets and heavier workloads across the entire region, if you may, across multiple data centers.
So this is something we have demonstrated in the field. It is field-proven with a customer of ours, and we hear a lot of chatter and people are looking for this solution as a way to mitigate the power shortage everyone is experiencing. And we have some great news coming your way. So if you are at the vicinity of Chicago in November, stop by SuperCompute ’26. This is the next major event for us.
Looking forward to SC26
We’re going to have some very exciting announcements there, both in terms of new customers we have, and we have a lot of new customers, And in terms of new solutions around orchestration, around building an AI infrastructure in an easier, faster, and more efficient manner. So don’t miss SuperCompute. Come and visit us there. Thank you.
Want to learn how DriveNets is reshaping AI infrastructure?
Explore DriveNets AI Fabric full stack networking solutions for AI Infrastructure